章节大纲
-
-
平时实验75分。参加现场答辩70%,删除某段代码可以5分钟复现100%,未能复现但思路正确80%。 最终成绩取得分最高的3次实验平均分。
书面综述报告满分5分。写法按小论文related work写法(中英文均可,要有类似however段落进行批判性总结分析)。
批判性口头报告(每位参与者将通过一到两篇代表性科学论文对一个研究主题进行详细研究。参与者将在约 30 分钟的演讲中介绍论文的主要思想。目标是其他参与者在演讲后理解报告人对两篇论文的批判性分析。)满分15分,可做多次取最高一次得分。
完成对批判点的改进实验,满分10分。
总计满分100分,操过100分按100分计。
报告 和 review模版 请大家注意 按此总结 多数情况下阅读的重点是:
A、文章讨论的核心问题是什么?一般不超过三个,会在abstract和introduction里强调出来。在related work文章是怎么评价相关工作存在的问题的。
B、各个核心问题的解法是什么?做了什么假设?
先看摘要,再看Introduction知道文章想要讨论的问题/现象,然后直接跳到最后的总结,然后跳到关键例子。这是一种“输入”型的阅读法。如果你的阅读目的是想为作者处理过的核心问题提出新的解法,想要“输出”,那这时还要加上:
C、各核心假设是基于什么样的证据和动因,论证是否充分?消融实验是否充分?
D、解法里使用了什么样的技术,用得对不对?
E、核心理论有什么样的prediction
基本要实现看完就能写review section的程度。
-
-
https://aiengineeringfromscratch.com/课程简介
《AI Engineering from Scratch》 是一套免费、开源(MIT)的 AI 工程自学课程,核心理念是 "You don't just learn AI. You build it. End-to-end. By hand."(不是学 AI,而是亲手把它端到端造出来)。
表格
项目 数据 课时数 523 节课 阶段(Phase) 20 个 总时长 约 342 小时 语言 Python / TypeScript / Rust / Julia 每节课产出 一个可复用产物(prompt、skill、agent、MCP server) 官网 aiengineeringfromscratch.com 仓库 github.com/rohitg00/ai-engineering-from-scratch(已克隆到你本地) 20 个阶段的全貌:
表格
阶段 主题 阶段 主题 00 环境与工具 10 从零造 LLM 01 数学基础 11 LLM 工程化 02 机器学习基础 12 多模态 03 深度学习核心 13 工具与协议(MCP 等) 04 计算机视觉 14 Agent 工程 05 NLP 15 自主系统 06 语音与音频 16 多智能体与集群 07 Transformer 深入 17 基础设施与生产部署 08 生成式 AI 18 伦理、安全与对齐 09 强化学习 19 毕业项目 不建议从第 1 课顺序刷到第 523 课。 课程提供 12 条职业路径(learning-paths/),比如:
- Applied AI Engineer(LLM 产品工程,12 节课约 15 小时)
- Agentic AI Engineer、AI Evaluation Engineer、AI Data Engineer、用 coding agent 做工程、MCP 路径、Agent Skills 路径、Claude 认证路径……
不知道自己从哪开始?仓库里有
skills/start-learning/定位导师,网页上有 prerequisites 指南。本课程从04计算机视觉开始。 -
1. 读章节内容(书本 / 网页)
- 每章包含完整的文字讲解、公式推导和代码走读
- 网页版有纸质书做不到的东西:可交互的动画图表(能看、能拖动)和每章自带评分的测验
2. 跑代码(GitHub 仓库)
- 仓库地址:
https://github.com/rohitg00/ai-engineering-from-scratch - 每章都有一个
code/目录,里面是可以直接运行、也可以改坏来试的完整实现 - 仓库是 "活的版本",会随领域发展更新;书本是带版本号的快照。两者不一致时,以仓库为准
3. 用 AI 助手当私教(关键功能)
- 网站提供了机器可读的课程索引:
https://aiengineeringfromscratch.com/llms.txt - 把下面这段提示词贴给 AI 助手,它就能帮你学习:
I am working through AI Engineering from Scratch, Volume 2: Deep Learning. Fetch https://aiengineeringfromscratch.com/llms.txt, find the lesson I name, and act as my tutor: quiz me on its Key Terms, review my solutions to its Exercises, and walk me through its code from the repository.
AI 会做三件事:
- 用 "关键术语" 考你
- 批改你做的课后习题
- 带你过一遍仓库里对应章节的代码
推荐的学习流程
- 在网站上打开某一章,读文字 + 玩动画 + 做自测测验
- 克隆仓库,找到对应章的
code/目录,把代码跑起来、改一改 - 遇到不懂的地方,把那段
llms.txt提示词给 AI,让它针对这一章当你的导师
-
两种方式都是 "让 AI 当你导师",但载体、门槛、持久度完全不同。
对比
表格
提示词方式 npx skills add做什么 把那段提示词贴给任意 AI(我、ChatGPT 网页版、Claude),它临时抓 llms.txt当导师把课程的 6 个导师技能安装到你本地的 coding agent(Codex、Claude Code 等) 需要安装吗 零安装,复制粘贴即可 需要 Node.js + npx + python3 + 一个支持 skill 的 coding agent 入口 手动贴提示词,手动说 "学第 X 课" 装完用命令调: /start-learning、/learn、/course-guide、/check-understanding 13进度记忆 无状态。AI 不知道你上次学到哪,每次靠对话记录 有持久进度。写进 LEARNING.md(或MCP-LEARNING.md),跨会话自动续读定位测验 你自己挑课 start-learning内置 10 题定位测验,自动算出你该从哪个 Phase 开始,生成个性化计划逐课推进 靠你说 "下一课" learn技能每次会话固定教一课:概念→数学→代码→测验卡住跳转 你描述问题,AI 找课 course-guide直接跳到覆盖你卡点的那一课跑代码 AI 只能讲,能不能跑看平台 在 coding agent 里直接跑命令、操作仓库、做可执行实验(需要本地克隆) 本质区别一句话
提示词方式是 "租" 一个导师,每次对话重新介绍自己;
npx skills add是把导师 "装" 进你的编程环境,它有你的学习档案、记得你进度、还能直接操作代码。怎么选
- 提示词方式轻量、随问随学,继续用这个就行。
- 什么时候值得装 npx:你打算系统上课、想要自动定位起点、要进度文件
LEARNING.md跨会话续读、并希望导师能在终端里直接帮你跑实验改代码 —— 那时再装,而且要在 Codex / Claude Code 这类 coding agent 里装。 - 两者不冲突:提示词方式管单课深读,npx 管整条学习路径的进度和定位。

-
对比(针对「跟 ai-engineering-from-scratch 上课」)
https://github.com/settings/education/benefits
Cline Codex CLI GitHub Copilot(学生认证后) Agent 循环 好:自主读文件、改代码、跑命令、多轮迭代 好:终端原生,能跑命令、读文件、多轮讲课 中:VSCode 内 Agent 模式能读写文件,但终端操作弱,循环深度不如前两个 主要短板 要自己配模型后端;配本地模型才免费 终端里用,不如编辑器直观;模型费用自理 只能用云端模型,接不了你局域网的 Bonsai-27B 课程 Skill 体验 支持 SKILL.md, start-learning/learn-xxx自然语言触发支持 SKILL.md, start-learning直接在终端讲课 + lab官方表格写得最完整, /skills斜杠命令很顺,/find-your-level、/learn-xxx直接在 Chat 里调绑卡要求 不绑卡(工具免费) 不绑卡(CLI 免费,接本地模型 $0) 学生认证后不绑卡(Education Pack 直接开通 Pro) 模型费用 看你接的模型;接 Bonsai-27B = $0 接本地模型 = $0;用云端 OpenAI 要订阅 学生免费,云端 GPT/Claude 模型随便用,不限额 额度限制 无限制(本地模型随便跑) 无限制(本地模型随便跑) 学生版 Pro 额度很高,日常上课写代码基本用不完 教学质量 取决于你接的模型(Bonsai-27B 三值量化,中等) 取决于你接的模型(同上) 云端模型(GPT/Claude),讲概念、讲原理明显比本地模型清楚 能不能接私有部署的大模型API如Qwen3.8 27B 能 能 不能,只能用 GitHub 的云端模型
-
-
-
- 申请github账号、教育认证github copilot、安装vscode、给vscode安装cline插件、给cline等agent装skill
- npx skills add rohitg00/ai-engineering-from-scratch
- git clone https://github.com/rohitg00/ai-engineering-from-scratch.git
- cd ai-engineering-from-scratch
-
先到 GitHub 网页新建一个空的私有仓库 ai-engineering-learning —— 关键:不要勾选 "Add a README"、.gitignore、license,否则首次 push 会冲突:
- 打开 https://github.com ,点右上角头像旁边的
+号(一排图标的最右边那个加号)。 - 在弹出菜单里点
New repository(新建仓库)。 - 进入 "Create a new repository" 页面,依次填:
- Repository name:填
ai-engineering-learning - Description(可选):随便写,比如
AI Engineering from Scratch 学习记录 - Public / Private:选
Private(⚠️ 一定要选私有,别用 Public)
- Repository name:填
- 往下滚动到 "Initialize this repository with:" 这一栏 ——
- 不勾
Add a README file - 不勾
Add .gitignore - 不勾
Choose a license
- 不勾
- 点页面最底部的绿色按钮
Create repository
- 打开 https://github.com ,点右上角头像旁边的
-
随后将课程仓库作为你自己的学习仓库推送:
git remote rename origin upstream # 原课程仓库改名为 upstream
git remote add origin git@github.com:YOUR_GITHUB_ID/ai-engineering-learning.git
git push -u origin main # 把你的学习基线推到自己仓库
然后检查:
bash git remote -v应看到类似:
origin    git@github.com:你的用户名/ai-engineering-learning.git (fetch)
origin    git@github.com:你的用户名/ai-engineering-learning.git (push)
upstream  https://github.com/rohitg00/ai-engineering-from-scratch.git (fetch)
upstream https://github.com/rohitg00/ai-engineering-from-scratch.git (push) - 在课程仓库根目录执行:npx skills add rohitg00/ai-engineering-from-scratch
- 指定具体哪节课后,再按课程说明,在 Cline 中调用:start-learning
-
确认一下双远端:
git remote -v应看到origin(你的私有库,读写)和upstream(课程库,只读)。 -
-
用 VS Code 打开课程仓库目录,Control + `打开vs code termial
- 如果之前建立个人目录就跳过此步,没有就
mkdir -p _mywork建议创建一个极短的进度文件:
bash touch _mywork/PROGRESS.md内容只需要类似:
text # Progress - Current lesson: Phase 04 / Lesson 13 / 3D Vision — Point Clouds & NeRFs - Current step: The Problem - Next: Read The Concept, then run the lesson code.它不是“额外笔记系统”,只是让另一台 Mac 打开仓库后知道你学到哪里。
-
你目前提示符显示:
(base) lee@macmini ...这说明你正处在 Conda 的
base环境。现在在仓库根目录执行:bash conda create -n aie-scratch python=3.11 pip -y含义:
aie-scratch  = 这门 AI Engineering from Scratch 课程专用环境名
python=3.11  = 独立 Python 3.11
pip          = 在这个独立环境中安装 requirements.txt 所需的 pip
-y           = 自动确认
完成后激活:
bash conda activate aie-scratch此时提示符必须从:
(base) lee@macmini ai-engineering-from-scratch %变为:
(aie-scratch) lee@macmini ai-engineering-from-scratch %这是最重要的检查点。只有看到
pip install -r requirements.txt(aie-scratch)后,才允许运行 pip 安装。
二、日常:
-
-
你的最小目录结构
保持最少目录:
ai-engineering-from-scratch/
├── phases/ # 课程原始内容:不改
└── _mywork/ # 你的内容:只在此处写
├── PROGRESS.md
└── p04-l13-3d-vision-nerf/
├── easy.py
├── medium.py
├── hard.py
└── <课程 Ship It 明确要求的文件> -
提交你的学习进度
git add _mywork
git commit -m "写这次commit都完成了啥"
git push origin main
三、定期:拉取课程更新(卡住或想追新课版时)
git fetch upstream
git merge upstream/main
# 只有当你改动过课程原文件时才会冲突;解决后:git add . && git commit
git push origin main
-
-
-
下面从用 VS Code 打开课程仓库文件夹开始,给你一套完整、固定的学习流程。核心原则是:
-
动态网页:负责“读课、看图、做互动测验、看课程导航与动画”。
-
VS Code:负责“看真实源码、运行代码、写自己的练习、Cline 辅导、查看 Git 改动、提交同步”。
-
Terminal:负责“环境、运行命令、Git、依赖安装、记录证据”。
0. 三个界面如何分工
先建立一个非常明确的判断规则。
- 用 VS Code 打开课程仓库目录,Control + `打开vs code termial :
- conda activate aie-scratch
- git pull --ff-only origin main
-
之后看网页、看 VS Code 里的课程文件、完成作业。
结束学习时
只提交你自己的
_mywork/: - git add _mywork
- git commit -m "study: phase 04 lesson 13 progress"
- git push origin main
每节课的内部结构(照着这个顺序读)
每节课的
docs/en.md固定八段,对应你的阅读顺序:The Problem → 不懂这个会怎样?建立动机 The Concept → 纯概念+图,建心智模型(不写代码) Build It → 从零分步实现,每段代码独立可跑 Use It → 框架/库怎么实现同一件事,对比你手写的 Ship It → 这节课产出的可复用 prompt/skill,存到 outputs/ Exercises → 3 题:Easy(巩固)/ Medium(迁移)/ Hard(综合) Key Terms → "别人怎么说 vs 实际是什么",一张表纠正误解 Further Reading → 延伸论文/资料一节课的完整闭环(八段 × 你的动作 × 五步法)
表格
顺序 固定八段 你的具体动作 官方五步法 0 (八段外) 课前 pre-quiz:quiz.json 里 stage= pre的题,建基线—— 1 The Problem 读,搞懂 "不懂这个会怎样" Read 2 The Concept 读,抓公式和图,建心智模型 Read 3 Build It ① 读 docs 里的代码块 → ② 跑 code/main.py逐模块看输出 → ③ 亲手重敲关键代码Read + Run + Type 4 Use It 读,对比手写版和库版(如 nerfstudio) Read 5 (八段外) 课后 post-quiz:stage= post的题,对比课前基线—— 6 Exercises 做 3 道题(Easy/Medium/Hard),自己写代码 Build 7 Ship It 对照 outputs/检查本课该产出的产物Keep evidence 8 Key Terms 用这张表自查 "别人怎么说 vs 实际是什么" —— 9 Further Reading 选读论文,可选 —— 关键点
- "跑 main.py" 只出现在第 3 步(Build It),不是独立环节。之前那张表里 "课中" 就是它,现在归位了。
- pre/post quiz 不属于八段,是叠加在八段前后的两次诊断,作用是让你看到自己的进步。
- "亲手敲代码"(五步法的 Type)也在 Build It 里,和跑 main.py 是同一阶段的两个动作:先跑通别人的,再自己敲一遍。
- 真正需要你写新代码的只有第 6 步 Exercises—— 其余都是读、跑、对照。
-
-
- 浏览器打开本课:3D Vision — Point Clouds & NeRFs
- 在 VS Code 中打开:phases/04-computer-vision/13-3d-vision-nerf/docs/en.md
- phases/04-computer-vision/13-3d-vision-nerf/code/main.py
- 打开 VS Code 的 Cline 面板。你可以先发一句简短指令:start-learning phase 04 lesson 13
-
`LEARNING.md` 已创建完成 ✅
**你的学习计划概要:**
- **入口点**:Phase 4: Computer Vision,从第 13 课「3D Vision (NeRF)」开始
- **预计学习量**:Phase 4 起到 Phase 19 共计约 **1053 小时**(按 ~5 小时/周计算)
- **任务表**:Phase 0-3 标记为 Skip,Phase 4-19 标记为 Do**接下来:**
- 运行 `learn`(Codex 环境)来启动第一课,它会自动读取并持续更新 `LEARNING.md`。
- 如果想跳到某个具体主题学习,可以用 `course-guide <topic>` 命令。
- 先读网页精读本地课程正文
docs/en.md按小节提问、检查理解理解当前学习位置_mywork/PROGRESS.md读取并据此恢复学习看真实实现code/main.py解释已有代码,不擅自修改执行程序、看报错VS Code Terminal根据你提供的真实输出分析写 Easy / Medium / Hard_mywork/p04-l13-3d-vision-nerf/澄清题目、审查代码、指出缺陷完成 Ship It_mywork/p04-l13-3d-vision-nerf/只核对课程原始要求 -
`
-
-
-
-
> **课程**:AI Engineering from Scratch · Phase 04 Computer Vision · Lesson 13
> (`phases/04-computer-vision/13-3d-vision-nerf`)
> **本专题**: —— 点云与 PointNet
当前学习到build it和exercise1的部分。即包含点云与 PointNet的部分。3D Vision — Point Clouds & NeRFs - AI Engineering from Scratch;网课定位
-
-
-
-
学生必须标记完成
https://3dgstutorial.github.io/index.html
3dgs cuda代码讲解 diff-gaussina-rasterization/cuda-rasterizer/forward.cu
41:41
-
-
-
-
学生必须标记完成
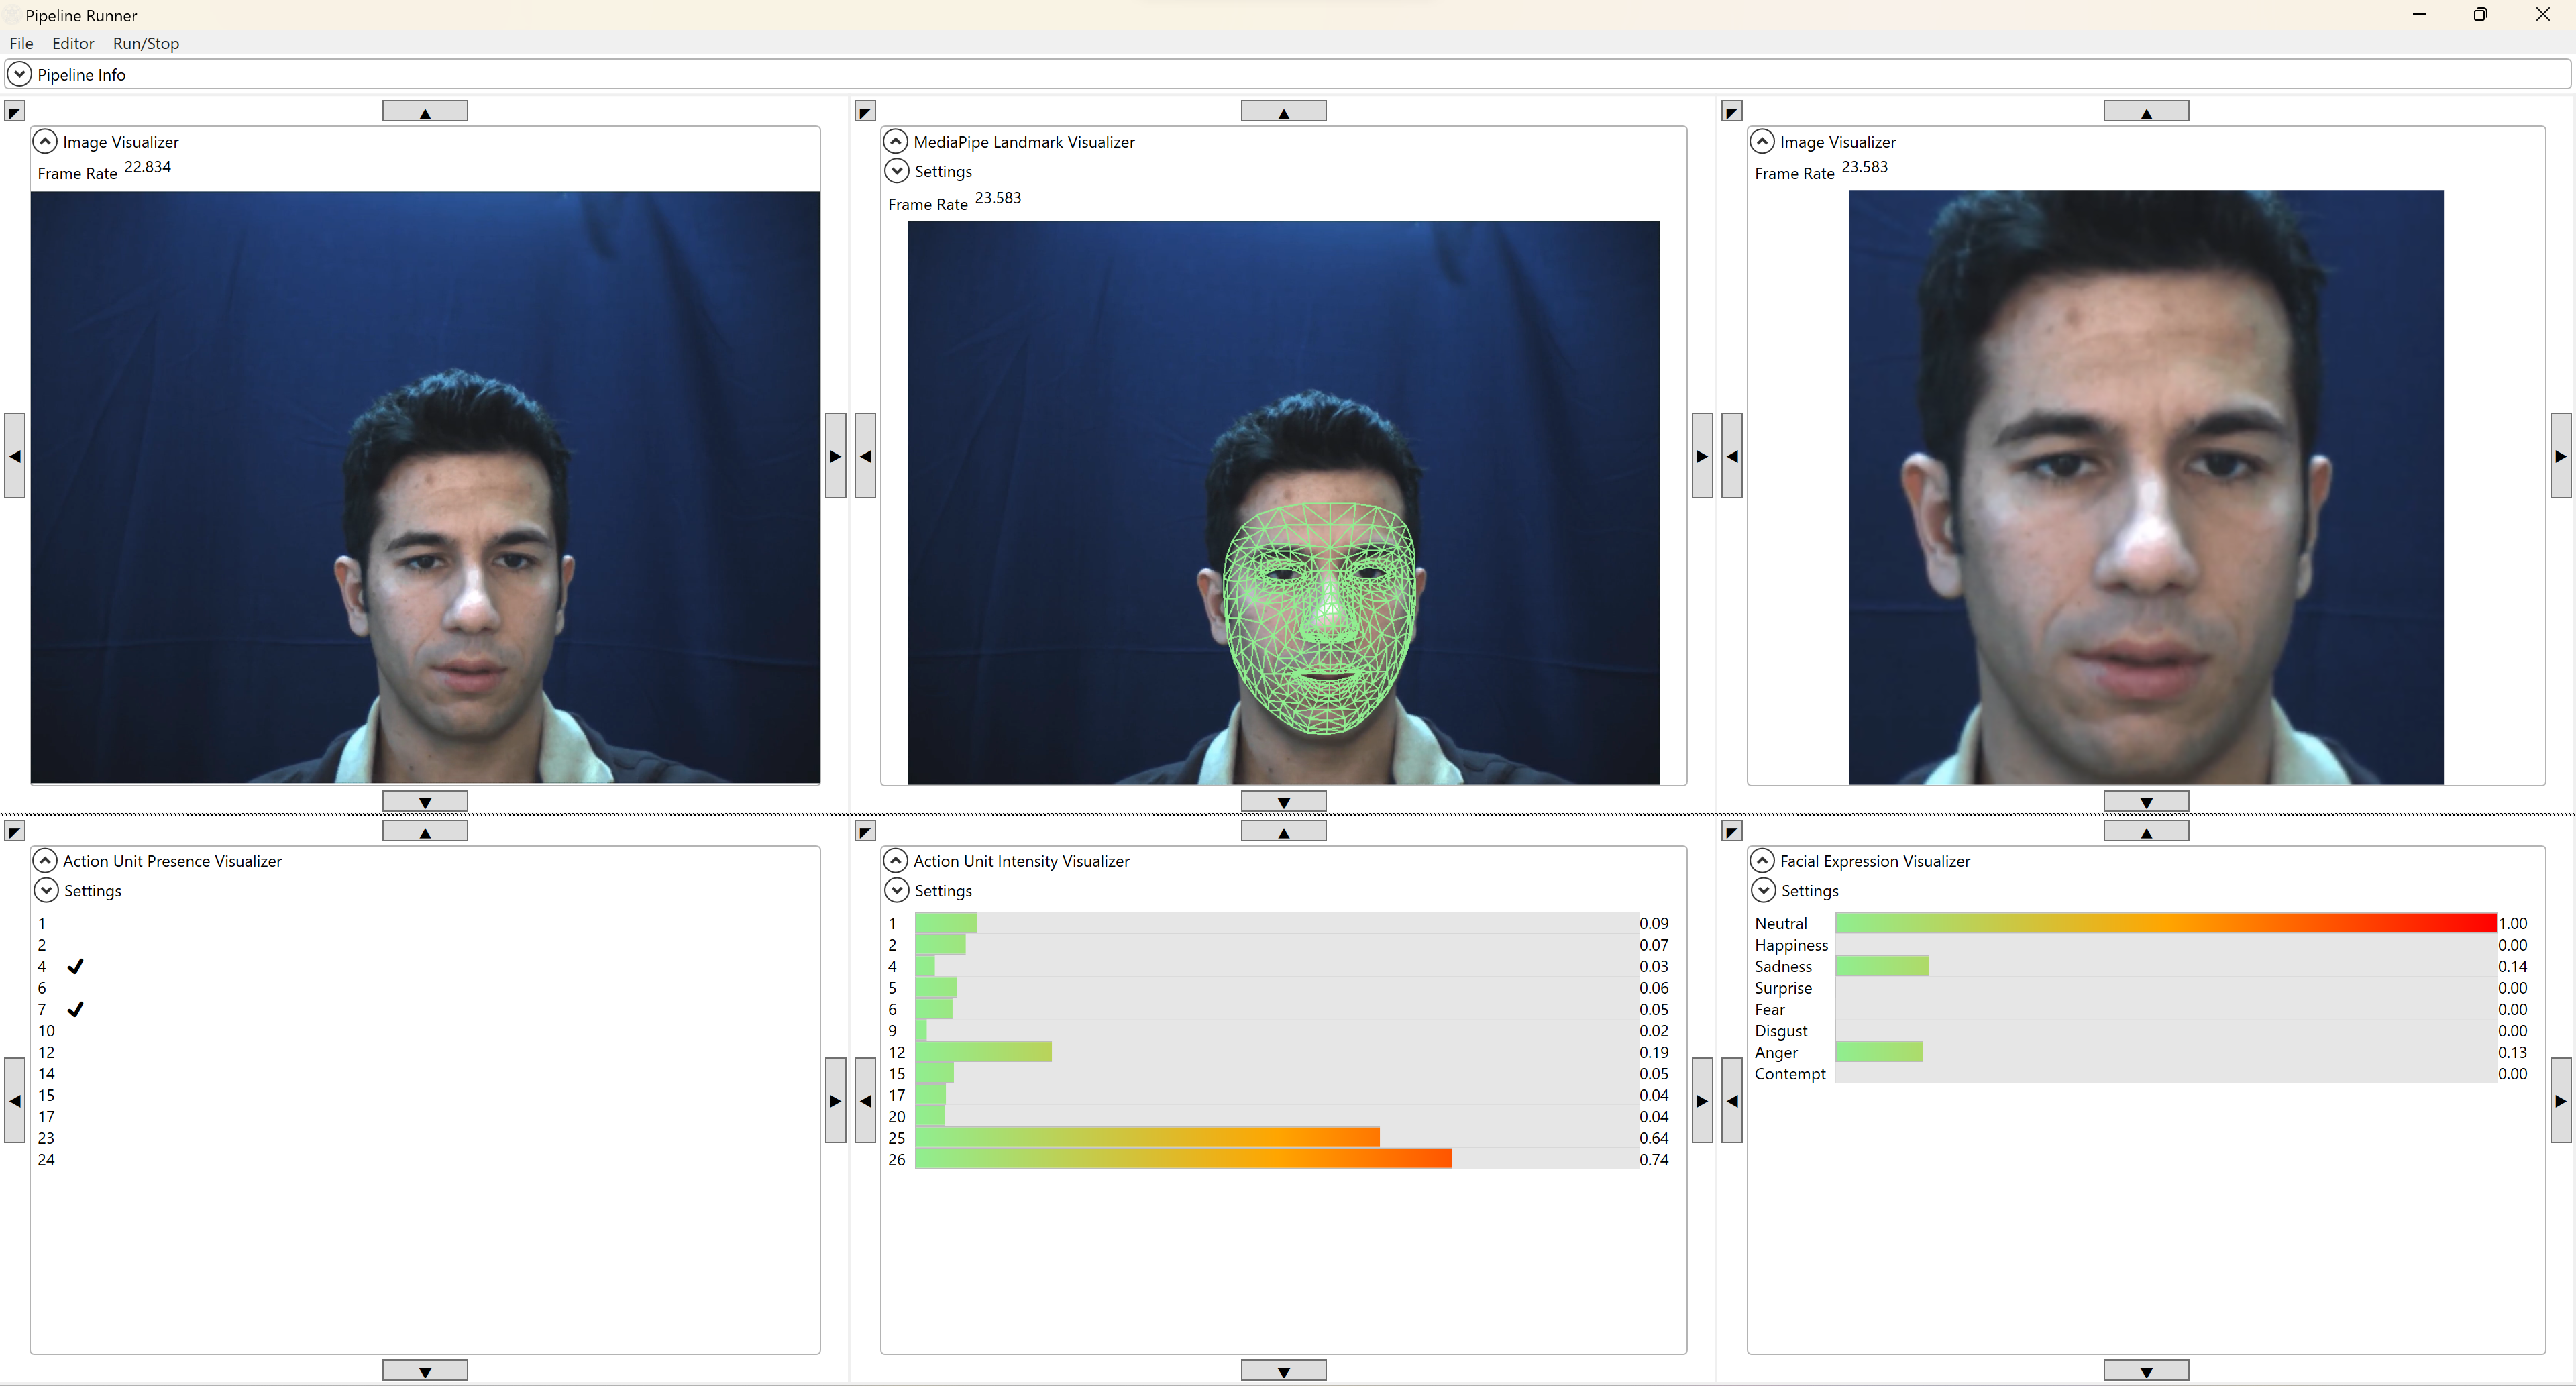
A full Face Analysis workshop in Python covers the following topic: - Create full web app from scratch using Gradio UI in Python - Processing Webcam input as Image and Video - Create Face Orientation on Face (Image/Video/Webcam) - Apply FaceDetect Algorithm - Apply FaceMesh (Image and Video) - Deploy full application to Hugging Face Space
https://github.com/prodramp/DeepWorks/tree/main/FaceProcessingWebcam
git clone https://github.com/prodramp/DeepWorks.git
cd DeepWorks/FaceProcessingWebcam/FaceAnalysisWebApp
conda create -n opencv_gradio python=3.8
conda activate opencv_gradio
pip install -r requirements.txt
建议所有环境配置问题直接问chatgpt比在网上找帖子排错高效。
然后继续在 PyCharm 中添加刚刚成功的Conda 环境opencv_gradio。

程序中不同版本gradio调用摄像头函数参数可能不同
如果安装的是gradio 4.39.0 原来程序的需要改为
webcam_image_in = gr.Image(label="Webcam Image Input")
webcam_video_in = gr.Video(label="Webcam Video Input")
requirements.txt 需要改为旧版mediapipe
mediapipe==0.10.10
-
学生必须标记完成
提交到 https://classroom.github.com/a/ZEZxzkh6
修改gradio窗口布局,完成全部作业后发布公网链接让朋友试用。
https://docs.opencv.org/4.x/dc/d2c/tutorial_real_time_pose.html 参考上面链接,修改代码。实现gdut校徽,贴人头上。有AR透视变换(同态映射)变换效果。
增加一个模型 Torchlm人脸检测库 :https://github.com/DefTruth/torchlm 新建一个tab: “models comparison”页。 要求UI为4窗口:1原图视频,1个原视频上叠加mediapipe(或Dlib)68点, 1个叠加Torchlm 68点, 1个叠加2个模型的对应点连线(线的长度反应了2个模型的定位差异)
-
-
-
-
-
学生必须标记完成
提交到
https://classroom.github.com/a/p_pWDT3Z
git clone https://github.com/GDUTCV/ <作业页面自动生成的> .git
cd hw01_image_formation/code/
Create a new environment named lecturecv and install required packages (numpy, etc.) via running:
conda env create -f environment.yml
Note: A typical source of error is to use an old version of conda itself. You can update it via:
conda update -n base conda -c anaconda
Before launching your notebook you need to activate the environment:
conda activate lecturecv
Depending on your configuration, you might instead need to run:
source activate lecturecv
You can now start jupyter notebook from the directory:
jupyter-notebook
A browser window should be opened in which you can open the notebook of the first exercise called image_formation.ipynb
也可以上传到colab然后做编程题。
也可以上传到google drive再用colab打开,此时需要加载drive文件夹
from google.colab import drive
drive.mount('/content/drive')
-
HAHA: Highly Articulated Gaussian Human Avatars with Textured Mesh Prior https://arxiv.org/pdf/2404.01053 https://github.com/david-svitov/HAHA/ Emergent Correspondence from Image Diffusion https://proceedings.neurips.cc/paper_files/paper/2023/file/0503f5dce343a1d06d16ba103dd52db1-Paper-Conference.pdf https://diffusionfeatures. github.io Recurrent Partial Kernel Network for Efficient Optical Flow Estimation https://hmorimitsu.com/publication/2024-aaai-rpknet/2024-aaai-rpknet.pdf https://github.com/hmorimitsu/ptlflow
-
-
-
-
学生必须标记完成
1.作业2 提交到https://classroom.github.com/a/gzMZO0nH阅读 https://github.com/ahojnnes/local-feature-evaluation/blob/master/INSTRUCTIONS.md 并配置环境 准备数据
2.运行理解代码 scripts/matching_pipeline.m
3.运行理解代码
scripts/reconstruction_pipeline.py4. 可视化论文图片结果
-
-
-
-
https://image-matching-workshop.github.io/cvpr2024/
- 14:00 - 14:45: Invited talk by Prof. Juan Tardós (Universidad de Zaragoza): Visual SLAM inside the human body
- https://zaguan.unizar.es/record/133189
- 14:45 - 15:00: Invited talk by Vincent Leroy (NAVER Labs): From DUSt3R to MASt3R
-
-
-
-
学生必须标记完成
阅读教材2第18章、 附录6、schoenberger_thesis的7 Structure-from-Motion Revisited
手写Bundle Adjustment对三维重建/SLAM研究的作用
-
-
-
10:00-11:20 Introduction to the tutorial and learning objectives. Overview of 3D body models, the history, mesh registration, linear blend skinning, SMPL and related models. Contents: history of body models, scanning, registration, PCA, linear blend skinning, corrective blend shapes, SMPL, faces, hands, SMPL-X, dynamics of soft tissue, future directions like implicit surfaces and neural rendering. Instructor: Michael Black
https://www.bilibili.com/video/BV1ysmtYjEYc/
11:20-11:40 Fitting SMPL to images using optimization. Instructor: Dimitrios Tzionas
https://www.bilibili.com/video/BV1Zom4YvEsy/
11:40-12:00 Regressing SMPL from images. Instructor: Timo Bolkart
-
-
-
-
-
https://www.bilibili.com/video/BV1NyzuYGELa
Sun, D., Yang, X., Liu, M.-Y., Kautz, J., 2018. Pwc-net: Cnns for optical flow using pyramid, warping, and cost volume In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition. pp. 8934–8943.
Sun, Deqing, et al. "Autoflow: Learning a better training set for optical flow." Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition. 2021.
https://www.bilibili.com/video/BV1R9zvYcEsr
Teed, Z., Deng, J., 2020. Raft: Recurrent all-pairs field transforms for optical flow In: Computer Vision–ECCV 2020: 16th European Conference, Glasgow, UK, August 23–28, 2020, Proceedings, Part II 16. Springer, pp. 402–419.
https://www.bilibili.com/video/BV1Ww4m117aY
Smith, C., Charatan, D., Tewari, A., & Sitzmann, V. (2024). FlowMap: High-Quality Camera Poses, Intrinsics, and Depth via Gradient Descent. arXiv preprint arXiv:2404.15259.
-
-
- 4DGS
- event camera
- 时空 transformer
de Blegiers, Tristan, et al. "EventTransAct: A video transformer-based framework for Event-camera based action recognition." 2023 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS). IEEE, 2023.
-
-
-
-
Robotics Foundation Models
π0: A Foundation Model for Robotics with Sergey Levine
Evaluating and Improving Steerability of Generalist Robot Policies
https://www.bilibili.com/video/BV1BcuJzdEpe
Time for Active Perception: See to Act, Act to See
-